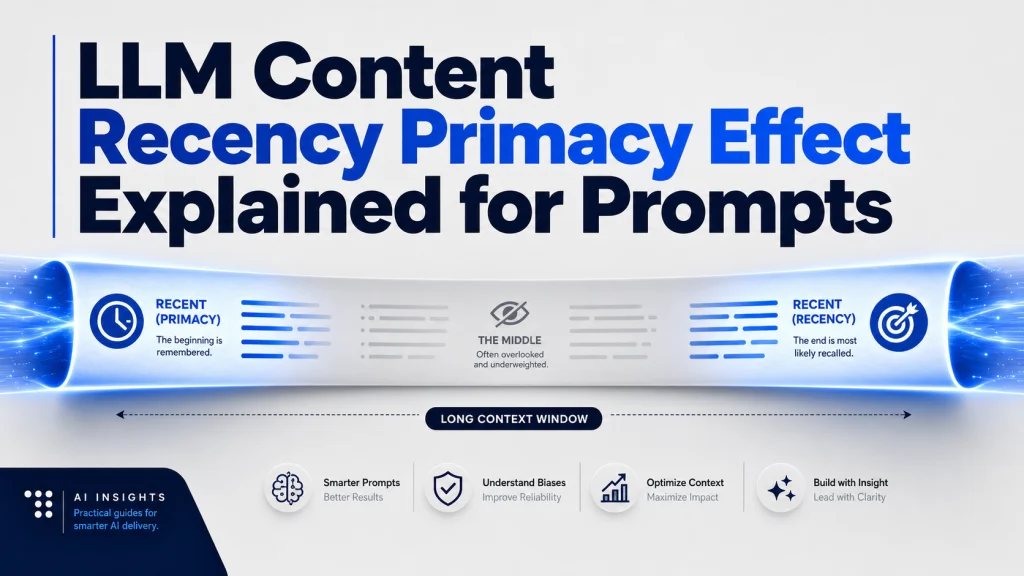
Put a must-follow rule in the middle of a long prompt and there’s a good chance the model skips it. That’s the LLM content recency primacy effect: language models weight the start and end of their context more than the middle. The core research is Liu et al.’s “Lost in the Middle,” backed by serial position and attention-bias studies covered below.
The effect is a positional tendency, not a universal law. Its size, and even its direction, shift with the model, the task and the length of the input.
It shapes both prompt results and which parts of your pages AI answers reuse.
Psychology gave the effect its name, but inside a model the cause is attention and token position, not memory. Move a skipped instruction to the first or last line and it usually survives.
- Primacy means the beginning of a prompt or context window gets extra weight. Recency means the end does.
- The middle is the weak zone, a pattern researchers call “lost in the middle.”
- The effect is a tendency that varies by model, task, and prompt structure. It is not a fixed rule.
- Placement can shape which facts a model uses and which content sections AI systems surface, but it does not guarantee accuracy or control.
What the LLM Content Recency Primacy Effect Is
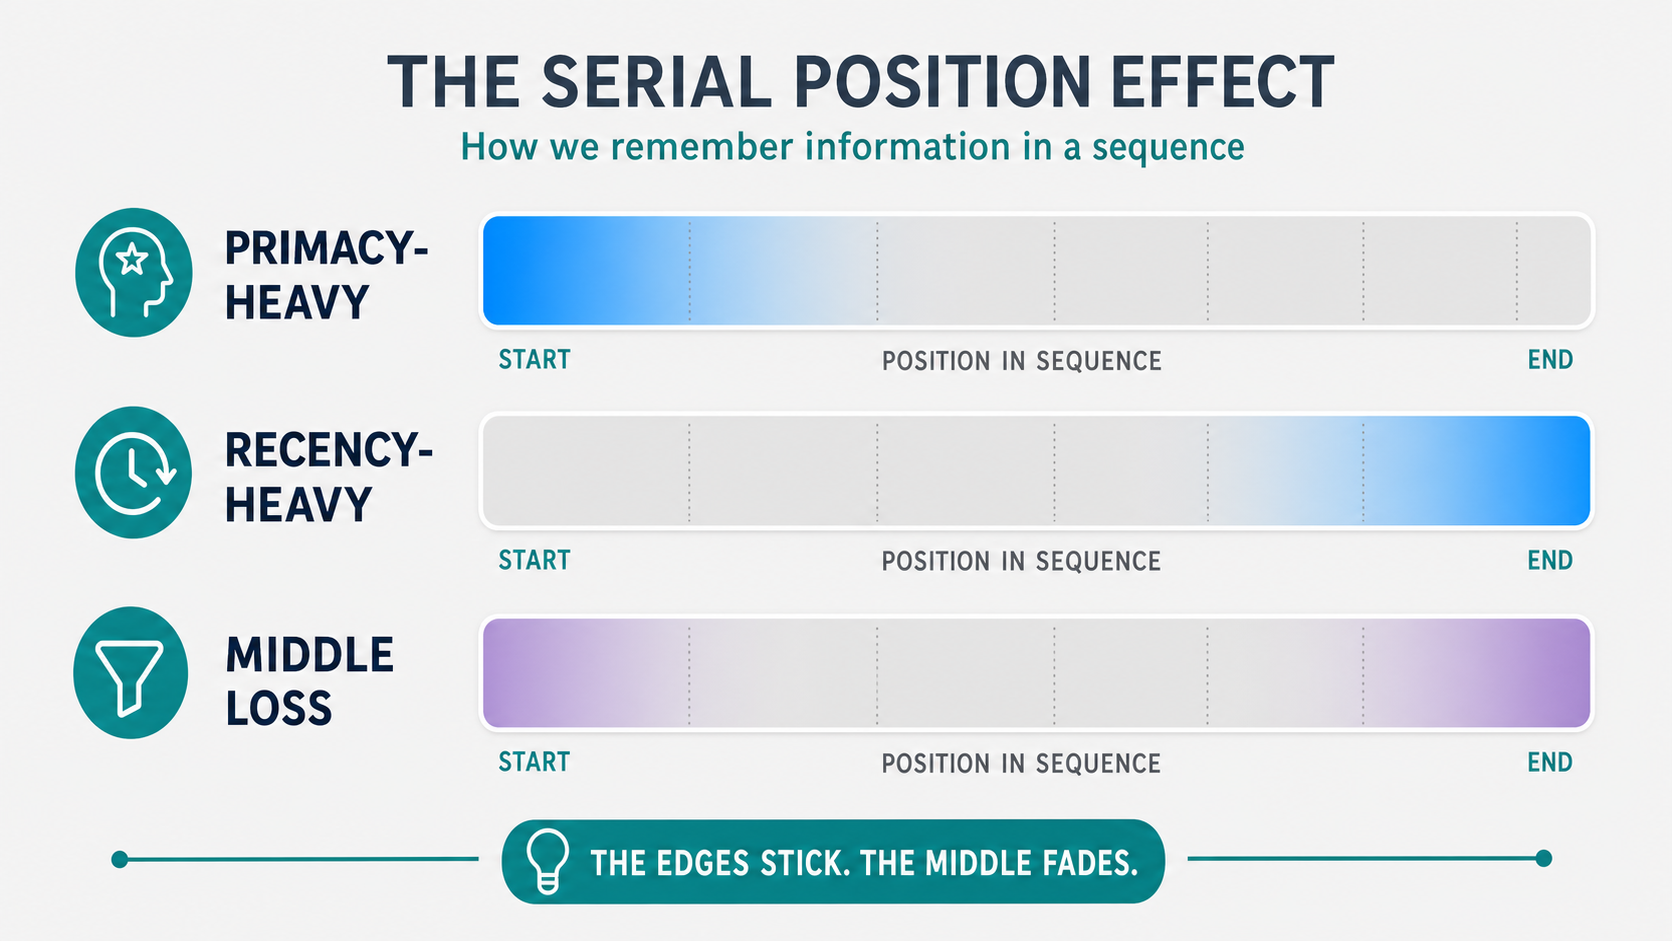
The LLM content recency primacy effect is the way language models give extra weight to information at the beginning and end of an input while underweighting the middle. It combines three related ideas.
Primacy is the extra weight content at the start of a prompt or context window receives. Early instructions, facts and examples often shape the response more than a neutral reading would justify.
Recency is the mirror image. Content at the end of a prompt also gets extra pull, and OpenAI’s GPT-4.1 prompting guide says the model tends to follow the later of two conflicting instructions.
The serial position effect is the umbrella term. It comes from cognitive psychology, where people recall the first and last items in a list better than the items in the middle. Researchers borrowed the label because the curve looks similar when you chart LLM behavior across token positions.
One clarification matters more than any other here. An LLM doesn’t “remember” the way a person does, and there’s no working memory holding the last few items.
What you’re seeing comes from attention distribution, positional encoding and patterns learned in training. The output looks human, but the cause is mechanical.
That distinction keeps you from overreaching. You aren’t appealing to a model’s short-term recall. You’re working with how the architecture spreads weight across positions, and that weight shifts with the task.
Why It Matters for Prompts, Answers, and AI Visibility
Position changes which facts a model reaches for when it builds an answer, and that matters for prompts and for AI visibility alike.
Instruction order in a long prompt isn’t cosmetic. It shapes instruction following, answer selection and, in retrieval-grounded systems, which passages get used.
A constraint at the end usually survives better than the same constraint dropped into the middle of a wall of text.
Content strategy inherits the same logic. AI search systems read your pages and pick which parts to reuse, so a claim you want quoted belongs in the opening summary or the closing recap, not halfway down.
That’s an inference from prompt research, not a measured web-page result. An answer-first content structure applies it section by section.
The pattern shows up across long-form content, retrieval-augmented generation workflows, and AI-generated summaries. In each case, the model is sampling from a sequence, and the edges of that sequence get a structural advantage.
One caveat keeps this useful. Placement influences output; it doesn’t guarantee it.
A well-placed instruction can still be ignored, and a well-placed claim can still go uncited. Treat position as a lever that shifts probabilities, not a switch that forces a result.
| Use case | What position affects | Practical consequence |
|---|---|---|
| Multi-instruction prompt | Which constraints the model follows | End and start instructions survive; middle ones slip |
| Long content page | Which sections get pulled into AI answers | Put quotable claims in the intro and the recap |
| Retrieved passages | Which passages the model actually reads | Mid-context documents can be underused even when relevant |
If you want the mechanics behind how systems choose what to cite, our guide on how AI crawlers actually pick sources pairs well with this section.
How It Works Inside LLM Context Windows
The recency primacy effect comes from how a model processes a sequence, not from any setting you can toggle.
Five mechanisms drive it.
1. Attention Distribution
The model assigns more salience to some tokens than others, and position influences that salience depending on the task.
2. Positional Encoding
Models tag each token with a position signal, so order is part of the information the model reads, not just the words themselves.
3. Instruction Placement
Where you put a directive changes whether the model treats it as top-priority guidance or background noise.
4. Training Data Ordering
Patterns in how examples were ordered during training and fine-tuning can shape positional tendencies in the finished model.
5. Context Truncation and Retrieval Limits
When input exceeds the window, what gets cut depends on the system. Some pipelines trim the middle, while OpenAI’s auto truncation drops the earliest items first. A retriever that caps its output cuts by relevance, not by position.
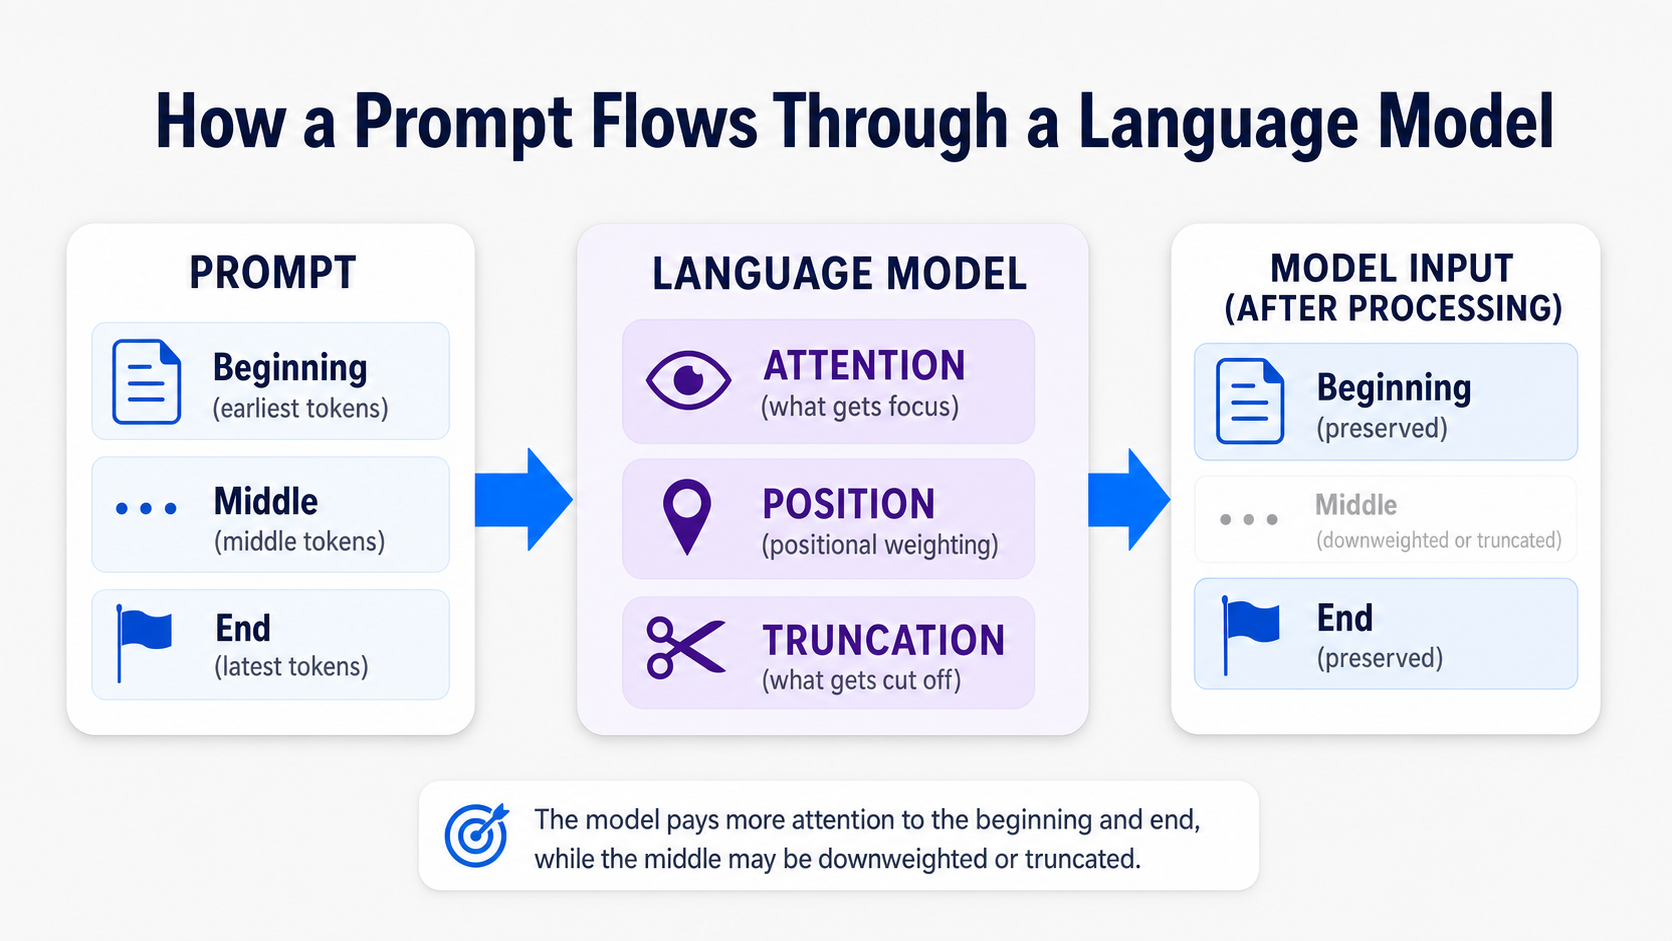
Task type tips the balance. Multiple-choice and classification work tends to lean primacy-heavy, with the model favoring earlier options. Summarization shows recency more often than classification does, though primacy still tends to win when both appear, especially in longer inputs. The same model can show different biases depending on what you ask it to do.
Long instruction lists are where this gets tested. The IFScale benchmark (2025) found almost no position bias when a prompt carries only a handful of instructions. As lists grew toward 150 to 200 instructions, models favored the earlier ones, so the later ones slipped first. If three rules truly can’t be missed, state them at the start and again at the end, as OpenAI’s GPT-4.1 guide recommends for long context.
The Four Main Forms to Know
The recency primacy effect splits into four forms you’ll meet in practice.
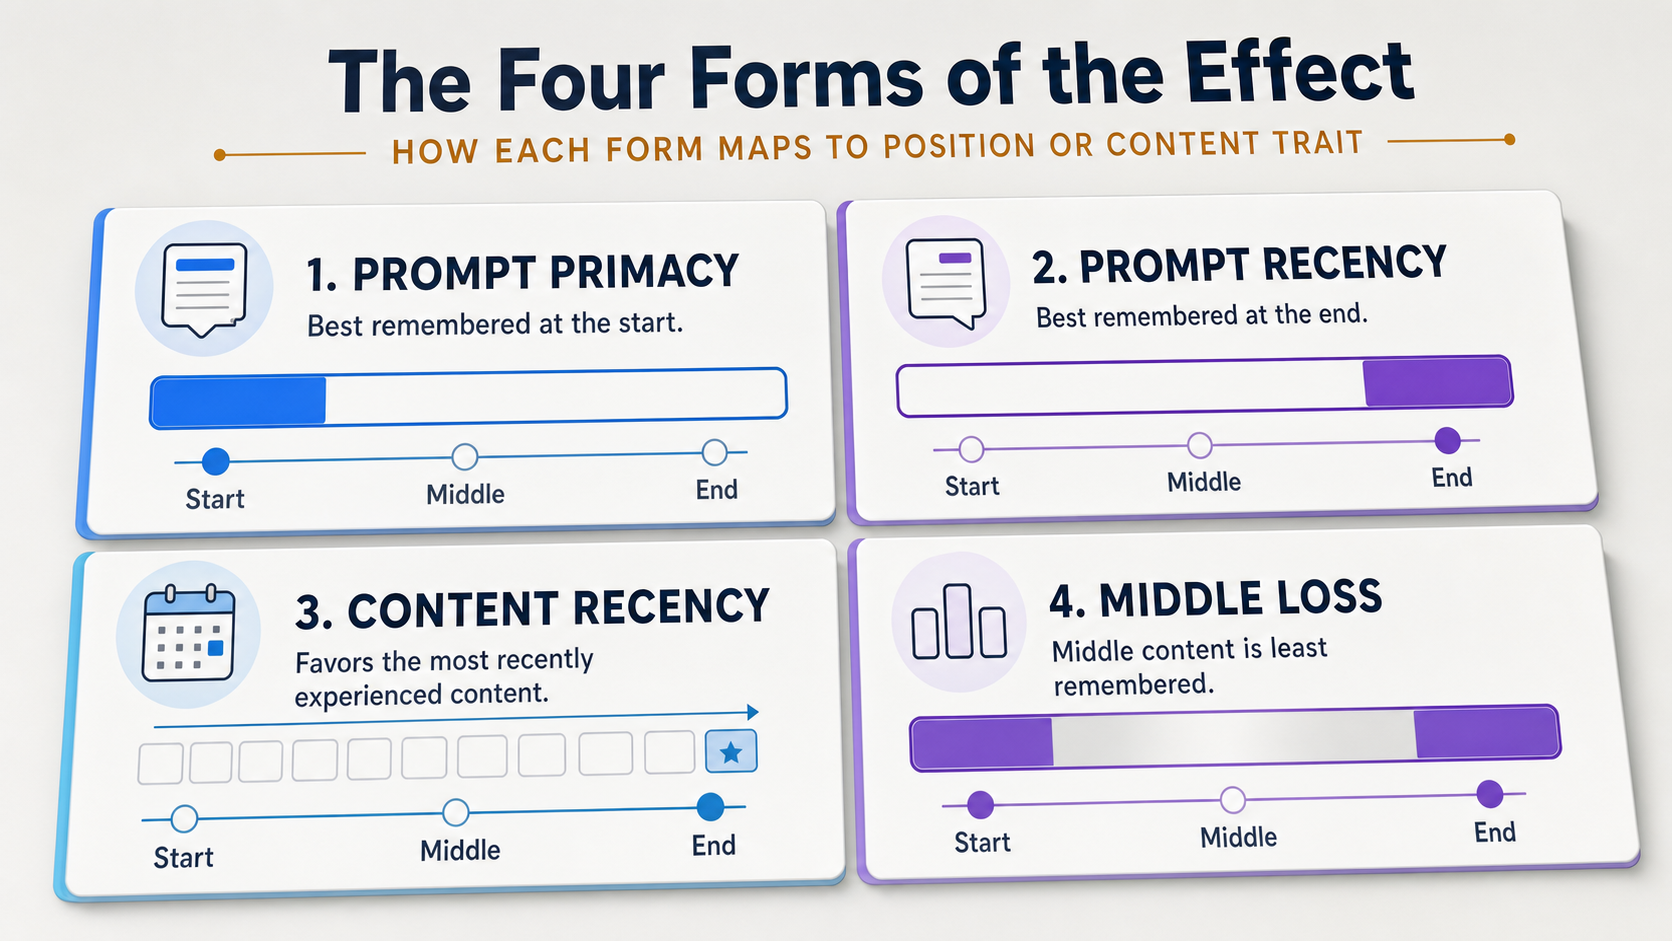
They’re related but not identical, and different systems show different combinations of them.
| Form | Where it shows up | What it means in practice |
|---|---|---|
| Prompt primacy | Early instructions and facts in a prompt | Opening directives and first examples get overweighted |
| Prompt recency | The latest instruction or example you give | The final instruction often wins when rules conflict |
| Content recency in AI citations | Fresher or recently updated pages | Some AI systems lean toward newer content when surfacing sources |
| Long-context middle loss | Information placed mid-window in long inputs | Relevant detail in the middle is easier for the model to overlook |
Prompt primacy and prompt recency are the two ends of the same curve, and you control both by deciding what goes first and last.
Content recency is a different animal. It’s about content age, not position within one input, and it interacts with authority and topic.
Middle loss connects them: it explains why everything that isn’t at an edge becomes vulnerable.
Teams running content audits often treat freshness as the only lever on citations. Placement and structure matter too, though that’s inferred from prompt research rather than measured against publish date.
Citations also shift between runs for reasons unrelated to either, covered in our guide on why LLM citations change and vanish.
What Research Papers Show on Position Bias
Research papers on LLM position bias agree on the direction: the edges of a context beat the middle. They don’t agree on the size, which shifts by model and task.
Peer-reviewed studies of serial position effects report primacy and recency biases across several model families, with primacy especially common in classification and multiple-choice settings.
Guo and Vosoughi (2024) found primacy in a clear majority of the instances they tested across open and closed models.
Liu et al.’s “Lost in the Middle” (Stanford, 2023 preprint, journal version 2024) is the cleanest demonstration of the weak zone. When the researchers moved the answer-bearing passage to the middle of a long context, question-answering accuracy dropped toward the level of a model with no documents at all.
Start and end placements held up far better. The same paper found extended-context models weren’t better at using their input than their shorter-context counterparts.
On the content side, Seer Interactive’s study of AI brand visibility and content recency found that freshness correlates with visibility, though the link varies by industry. Treat that as a correlation worth acting on, not a guarantee.
| Study type | Task | Observed bias | Takeaway |
|---|---|---|---|
| Serial position analysis | Classification, multiple-choice | Primacy dominant | Early options get favored across model families |
| Long-context question answering | Multi-document retrieval | Middle loss | Mid-context answers fall toward no-context accuracy |
| Summarization studies | Generation | Recency shows up more than in classification | Primacy still usually wins, especially in longer inputs |
| Applied content analysis | AI citation behavior | Recency in citations | Fresh content correlates with visibility, varies by vertical |
The practical lesson sits in the variation. Model family, instruction tuning and task format change the size and even the direction of the bias.
A prompt structure that works on one model isn’t a rule on the next. “It worked once” isn’t “it works.”
Attention Drift and Attention Sinks
“Attention drift” isn’t a formal term in the research papers. It’s a practitioner label for the way focus on mid-context material fades as input grows, which researchers study as positional attention bias.
Hsieh et al.’s “Found in the Middle” (2024) traced the U-shape to attention itself: tokens at the start and end of the input draw more attention regardless of relevance. Calibrating that positional bias improved how models used documents placed in the middle.
Xiao et al. (2023) described “attention sinks,” where models park a large share of attention on the first few tokens even when those tokens carry little meaning. Read these papers alongside Liu et al. before you trust any prompt-ordering advice.
Common Mistakes and Misconceptions
Most errors here come from treating a tendency as a law.
Assuming All LLMs Behave the Same
Bias direction and strength differ across model families and versions, so test each model instead of transferring assumptions.
Assuming Recency Always Wins
Primacy dominates many classification and multiple-choice tasks, so the last item doesn’t automatically take precedence.
Assuming Freshness Alone Drives Citations
Authority, relevance, and topic stability matter alongside content age, and freshness without substance rarely earns a citation.
Treating the Effect as a Fixed Law
It’s a probabilistic tendency that shifts with task and model, not a constant you can rely on.
Believing Prompt Ordering Guarantees Accuracy
Good placement raises the odds that important content gets used. It doesn’t force correctness or control.
Forgetting That Placement Coexists With Other Failures
A well-positioned instruction can still meet hallucination, refusal, or weak reasoning.
The trap that catches teams most often is overfitting to a single prompt win and generalizing it across models. That’s how a tactic that looked reliable in testing produces inconsistent results in production.
If you are building a repeatable process around this, our framework for diagnosing visibility and the AI overview optimization checklist give you a structured way to test placement assumptions instead of trusting one result.
Put Must-Follow Rules at Both Edges of Your Prompt
Pick your longest system prompt this week and list the three rules the model breaks most often. Move them to the opening lines and restate them in the final lines.
Then run the same set of test inputs before and after the change, on every model you ship to. Keep the version that holds up across models, not the one that won a single run.
Pages follow the same rule: the claim you want an AI answer to quote belongs in the first paragraph and the recap, never only in the middle.
Frequently asked questions
Do LLMs have a primacy bias?
Yes, many do. Research on serial position effects reports primacy appearing across multiple model families, and it shows up especially often in classification and multiple-choice tasks where the model tends to favor earlier options. The strength varies by model and task, so treat it as a documented tendency rather than a guarantee.
Does recency bias always beat primacy bias in ChatGPT?
No. Recency tends to appear more in summarization and some generation tasks, while primacy often dominates multiple-choice and classification work. Which one shows up depends on the task format, the model version, and how the prompt is structured, so neither bias automatically wins.
Why do LLMs miss information in the middle of long prompts?
The middle of a long context gets less positional weight than the edges, a pattern researchers call “lost in the middle.” When an answer-bearing passage sits in the center of a long input, accuracy can fall toward the level of a model working with no relevant context at all, while start and end placements hold up much better.
Is the serial position effect the same as the recency primacy effect?
They describe the same underlying pattern. The serial position effect is the umbrella term for the start-and-end advantage, and primacy and recency are its two halves. In an LLM context, the cause is attention and positional weighting rather than human memory, even though the curve looks similar.
Does putting important text at the start improve AI citations?
It can raise the odds. Opening summaries and clear early statements are structurally easier for AI systems to surface and reuse than detail buried mid-page. It does not guarantee a citation, because authority, relevance, and content freshness also influence whether your content gets pulled into an answer.
For more research-backed context on how language models find and cite sources, explore our AI Visibility Resources. You can also see how this plays out in monitoring with our guide on tracking brand mentions in large language models.
What is LLM attention drift?
LLM attention drift is an informal name for the fading focus a model gives mid-context material as input grows longer. Research papers study it as positional attention bias, “lost in the middle” and attention sinks. The fix in practice is placement: keep critical instructions and facts at the start or end of the context.
Does a bigger context window fix the lost in the middle problem?
No. Liu et al. found that extended-context models weren’t better at using their input than their shorter-context versions. A larger window lets you fit more text, but the middle of that text is still the weak zone.