For 14 days we counted crawler visits twice, in our server log and at Cloudflare. The server log missed 37% of genuine crawler page fetches, and it counted thousands of requests that only borrowed a crawler’s name.
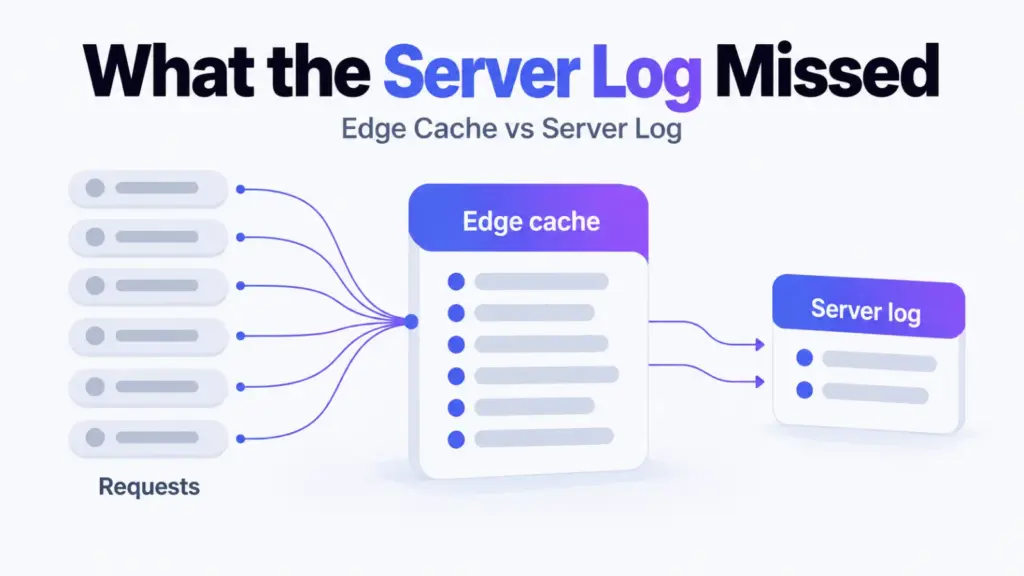
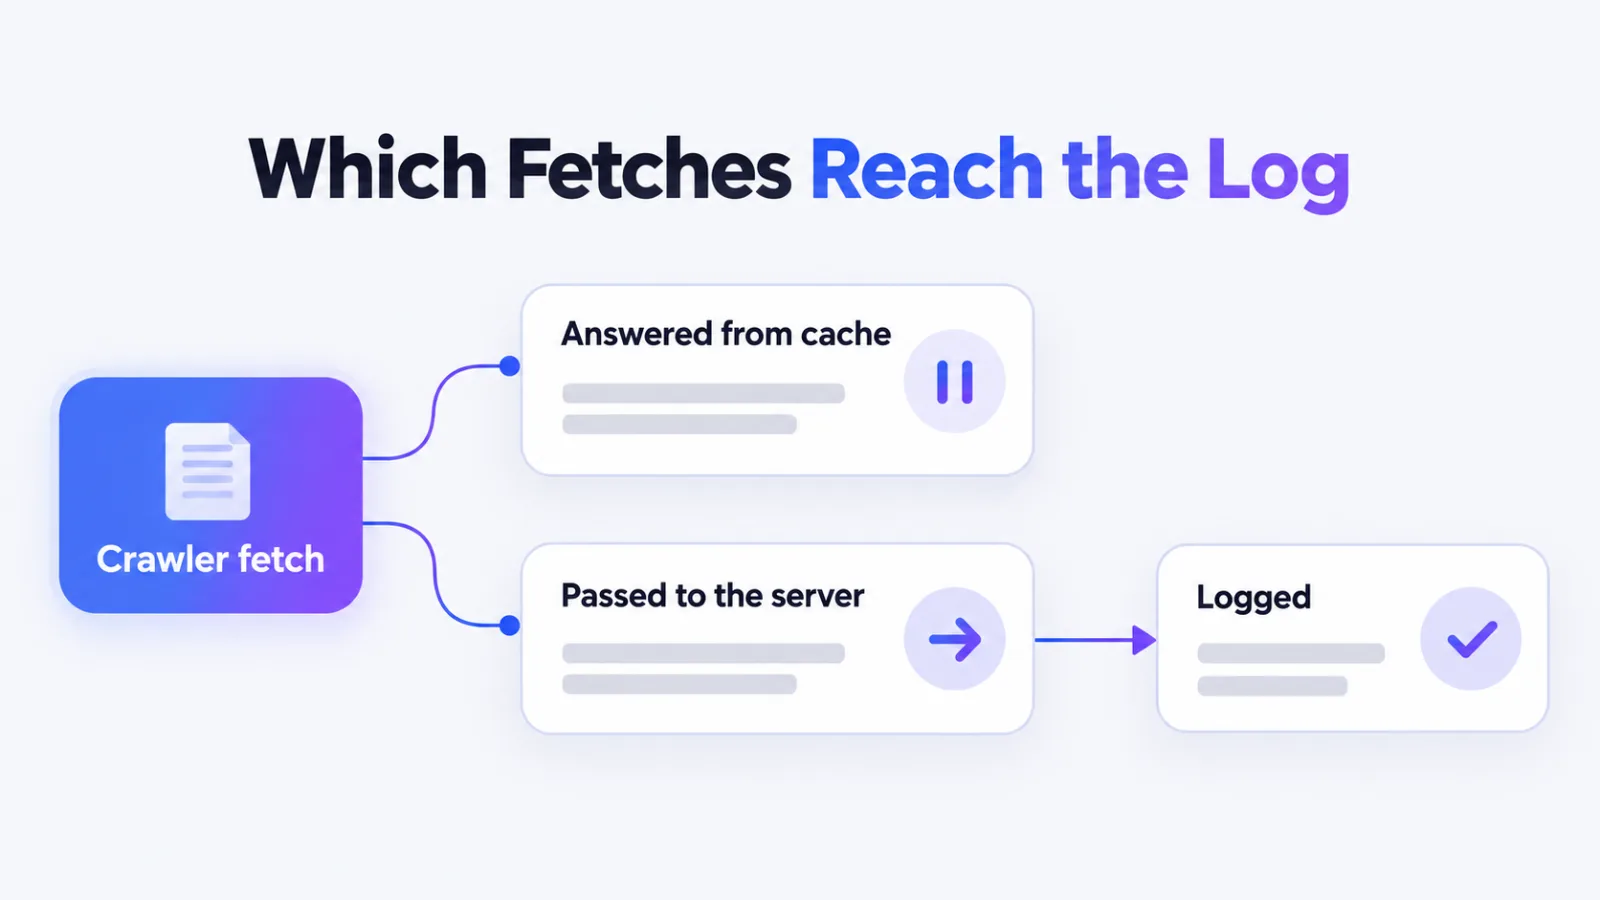
A server log sits behind the CDN, the network that delivers a site’s pages. When the CDN answers a request from its own stored copy, the server never hears about it.
Here’s what each source saw, which crawlers the log undercounted, how often a name was borrowed, and how to check your own site.
What We Measured
Fourteen full days, 22 September to 5 October 2026, on this site, from two sources at once.
- At the server: the access log, every request that reached our web server.
- At the CDN: Cloudflare’s analytics, including requests it answered itself.
- Page fetch: a successful request for a page, not an image or a script.
- Genuine: verified by Cloudflare, or sent from the operator’s published addresses.
The user agent is the name a visitor’s software gives itself. Behind a CDN, our server log has nothing else to identify a crawler. Cloudflare also sees the sending address.
The two sources agreed on what reached the server
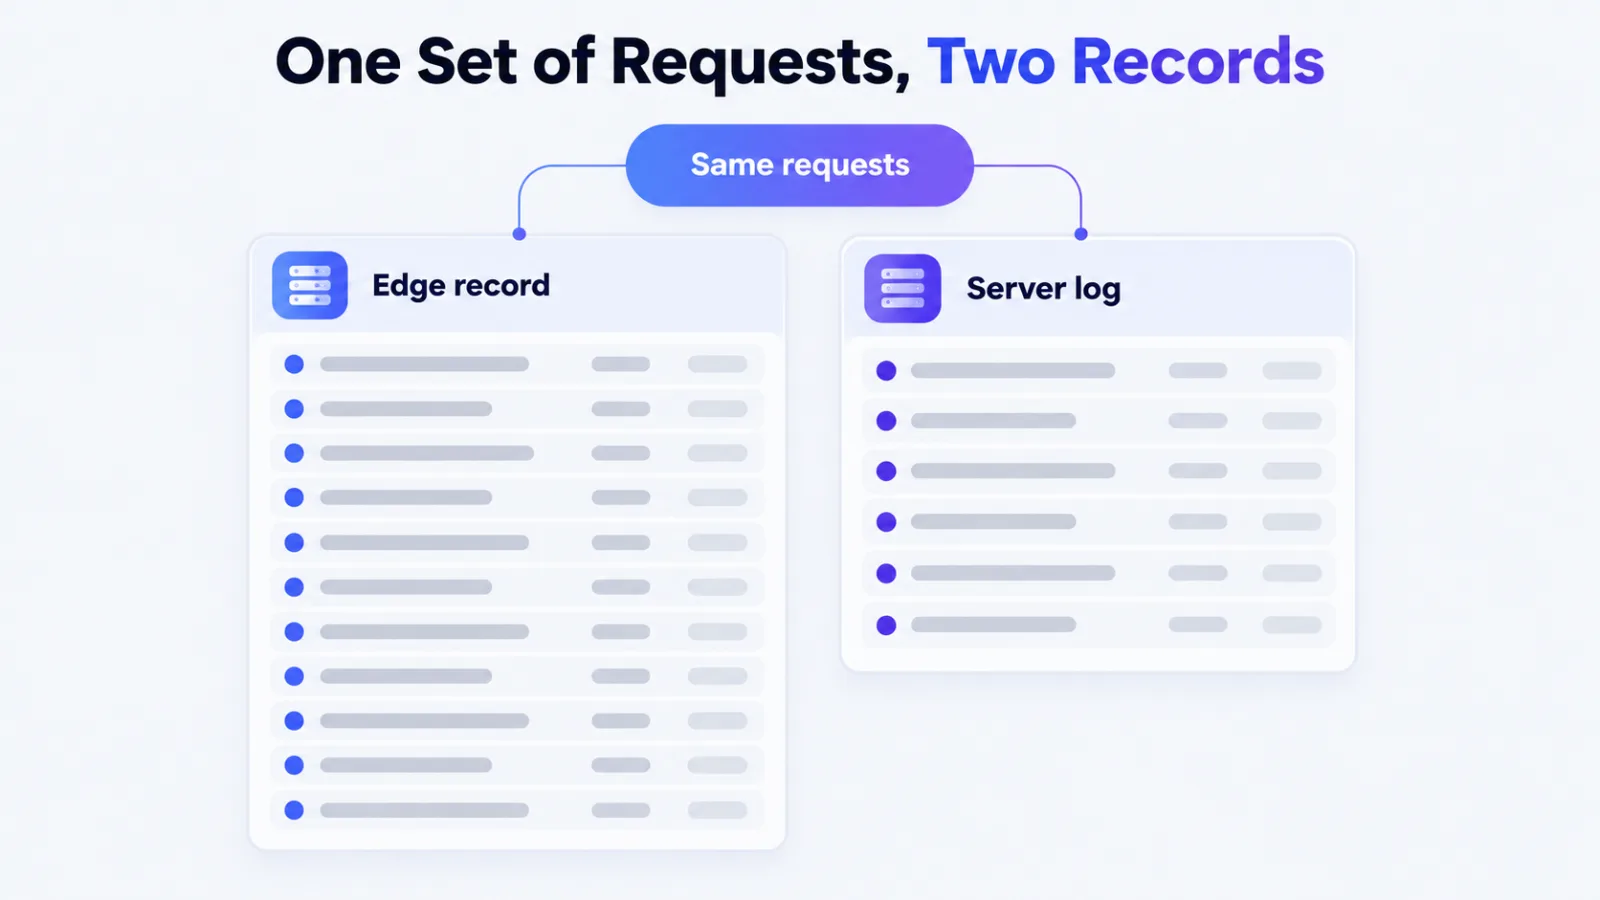
Before comparing them, we checked that both describe the same traffic. Across nine crawler names, the log held 2,539 page fetches and Cloudflare counted 2,532 that it passed to the server.
That’s 0.3% apart, so the gaps below aren’t a counting error.
What the Server Log Never Saw
Cloudflare answered 2,794 of 7,526 genuine crawler page fetches from its cache. That’s 37% of them, and none reached the server log.
A cache hit is a request the CDN answers from a stored copy of the page. We checked one day of ChatGPT-User fetches line by line. All 17 that Cloudflare passed on matched a log line within three seconds, and none of the 9 cache hits did.
| Crawler | Cached | Genuine page fetches | Answered from cache |
|---|---|---|---|
| meta-externalagent | 62% | 1,583 | 983 |
| ChatGPT-User | 43% | 361 | 156 |
| Bingbot | 32% | 737 | 235 |
| ClaudeBot | 32% | 138 | 44 |
| PerplexityBot | 31% | 440 | 135 |
| OAI-SearchBot | 27% | 281 | 75 |
| Googlebot | 23% | 325 | 75 |
| Amazonbot | 22% | 696 | 153 |
| GPTBot | 11% | 121 | 13 |
| All Cloudflare-verified crawlers | 37% | 7,526 | 2,794 |
ChatGPT-User is the fetcher OpenAI sends when a person’s chat reads a page. The log missed 43% of its fetches, and 62% of Meta’s.
PerplexityBot’s row uses Perplexity’s own address list, because Cloudflare doesn’t label that crawler.
The busiest pages lost the most
Genuine crawlers fetched the homepage 435 times, and 67% of those fetches came from cache. On eight of the ten most-fetched other pages, more than half did.
Search Console demand pointed the same way. Among the third of pages with the fewest impressions, 34% of fetches came from cache, and among the tenth with the most, 44% did.
What the Server Log Counted That Wasn’t Real
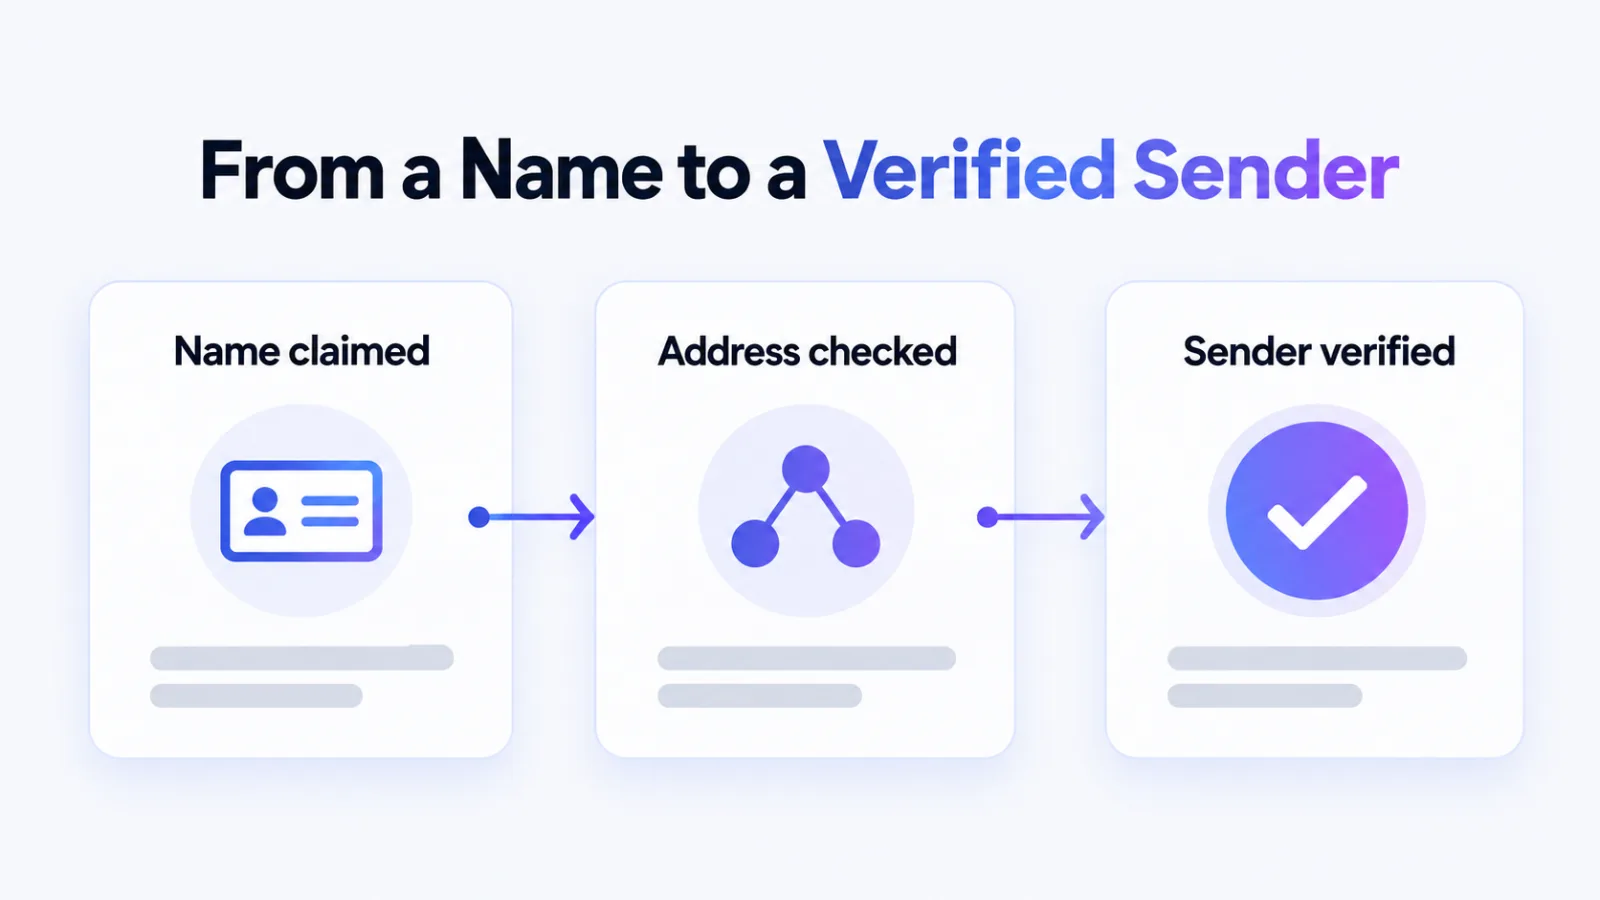
A log takes the user agent at its word, and a user agent can be copied. Cloudflare checks the sending address, so it can tell a crawler from a request using its name.
| Name in the user agent | Share genuine | Requests | Genuine |
|---|---|---|---|
| Bingbot | 100% | 3,073 | 3,073 |
| meta-externalagent | 98% | 8,159 | 8,014 |
| GPTBot | 87% | 1,700 | 1,485 |
| OAI-SearchBot | 83% | 1,136 | 943 |
| ClaudeBot | 78% | 1,165 | 914 |
| PerplexityBot | 75% | 708 | 529 |
| ChatGPT-User | 62% | 590 | 366 |
| CCBot | 44% | 387 | 170 |
| Bytespider | 30% | 3,813 | 1,128 |
| Claude-User | 17% | 290 | 49 |
| Googlebot | 10% | 13,225 | 1,263 |
| Perplexity-User | 0% | 153 | 0 |
Bingbot was always what it said it was, and Meta’s crawler nearly always. One request in ten using Googlebot’s name was Google’s.
Two checks gave one answer
We tested Cloudflare’s label against the address lists that Google, Microsoft, OpenAI and Perplexity publish for their own crawlers. Of more than 13,000 requests using Googlebot’s name, the two checks disagreed on 2.
Cloudflare doesn’t label PerplexityBot, Perplexity-User or CCBot, so for those three we used the operator’s list alone.
The fake Googlebot hit four pages
The 11,962 impostor requests came from 3,259 addresses, at about 850 a day, around the clock. In the 30 days we could see, they didn’t miss a day.
Four pages took 98% of them. One page alone took 8,670 fetches in the 14 days, and Search Console shows it earned 80 impressions in 90 days and no clicks.
Cloudflare answered 93% of those requests from cache, so the server log saw 7% of them.
What It Did to Our Own Numbers
Three of our earlier studies read the server log alone, so we re-checked each one.
Our ChatGPT-User visits study counted 270 page fetches. Cloudflare shows 361 genuine ones. The log saw 205 of them, and about 60 of its 270 weren’t OpenAI’s.
We re-ran that study on the verified fetches. Its conclusion held: page demand still predicted visits and rank still didn’t. Its counts changed.
Our study of new page crawl times dated PerplexityBot’s first visit to a new post at a median of 63 hours. Its first fetch was a cache hit on six of eight posts, and the real median was about 10 hours.
Googlebot’s times didn’t move. Its first fetch of all eight posts was genuine and reached the server.
Our fake AI crawlers study judged secret-hunting requests by their behaviour. Cloudflare backs it. We matched 574 of those requests to its records, and they came from six addresses, none of them a verified crawler’s.
Nine Sites, the Same Impostors
We ran the same 14 days on nine sites we manage, 2.56 million requests in all. The borrowed names showed up on every one.
- Googlebot: 36% genuine, of 35,355 requests using the name.
- ChatGPT-User: 71% genuine, of 6,551.
- GPTBot: 90% genuine, of 15,724.
- ClaudeBot: 93% genuine, of 19,559.
- Bingbot: 99.7% genuine, of 41,024.
By site, Googlebot’s genuine share ran from 10% to 99%.
The cache gap is different, because it depends on setup. Three of the nine sites store pages at the CDN, and there the cache answered 37% of genuine crawler page fetches. On five others the server log saw every fetch.
Cloudflare only stores pages when it’s set to, and a caching plugin may have set it for you. That’s why the first check below is a single response header.
What the Numbers Don’t Prove
Four limits, and the first two matter most.
- Estimates, not counts: Cloudflare samples its analytics when traffic spikes.
- One setup: the gap exists only where the CDN stores pages.
- Labels have gaps: some crawlers can’t be verified by either check.
- Fourteen days: cache purges and crawl bursts move the shares.
For the impostor Googlebot count, Cloudflare’s own 95% range is 11,896 to 12,028. Counts of genuine crawlers were rarely sampled at all.
We also purged the cache while editing pages in the window. Each purge sends the next fetch of every page back to the server, so a site that edits less would lose more.
An unverified request isn’t always a fake, because an operator can add addresses before a list catches up. Where two checks agreed, as with Googlebot, we’re confident.
How to Check Your Own Site
You need your CDN’s analytics and your server log for the same days.
- Look at one page: check its cf-cache-status response header for HIT.
- Count at the CDN: group requests by user agent and cache status.
- Verify the name: use the verified-bot label or the operator’s address list.
- Add both back: report genuine fetches, cache hits included.
- Keep the log: it’s complete for what reaches your server.
To see which crawlers reach you at all, start with which AI bots reach your site.
Frequently Asked Questions
Does a CDN hide crawler visits from a server log
Yes, when it stores pages. A request the CDN answers from its cache never reaches the server, so the log has no line for it. On our site that was 37% of genuine crawler page fetches.
How do I know if my pages are cached at the CDN
You can check the response headers of any page. On Cloudflare, a cf-cache-status of HIT means the CDN answered from its stored copy.
What share of Googlebot requests are fake
On our site, nine in ten requests using Googlebot’s name weren’t Google’s. Across nine sites it was 64%, and it ran from 1% to 90% by site.
Can I trust the user agent in a server log
No. It’s text the sender chooses. Check the sending address against the operator’s published list, or use your CDN’s verified-bot label.
Is a server log still worth keeping
Yes. It’s complete for every request that reaches your server, and CDN analytics are sampled. You need both to count crawlers.
Count at the CDN, Then at the Server
Our server log told us less than it seemed to. It missed a third of genuine crawler fetches and took thousands of borrowed names at their word.
Pull the same 14 days from your CDN before your next crawler report.