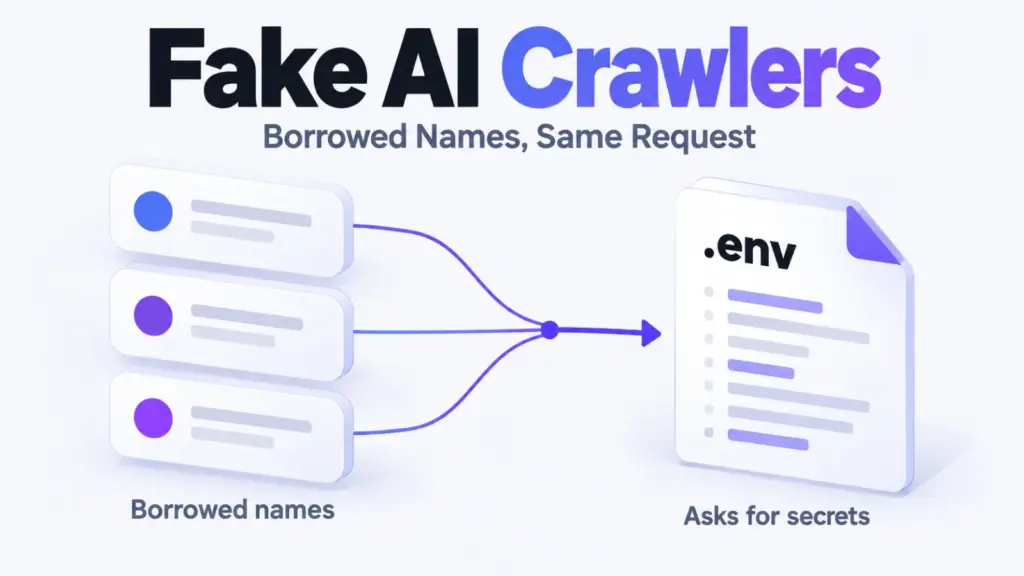
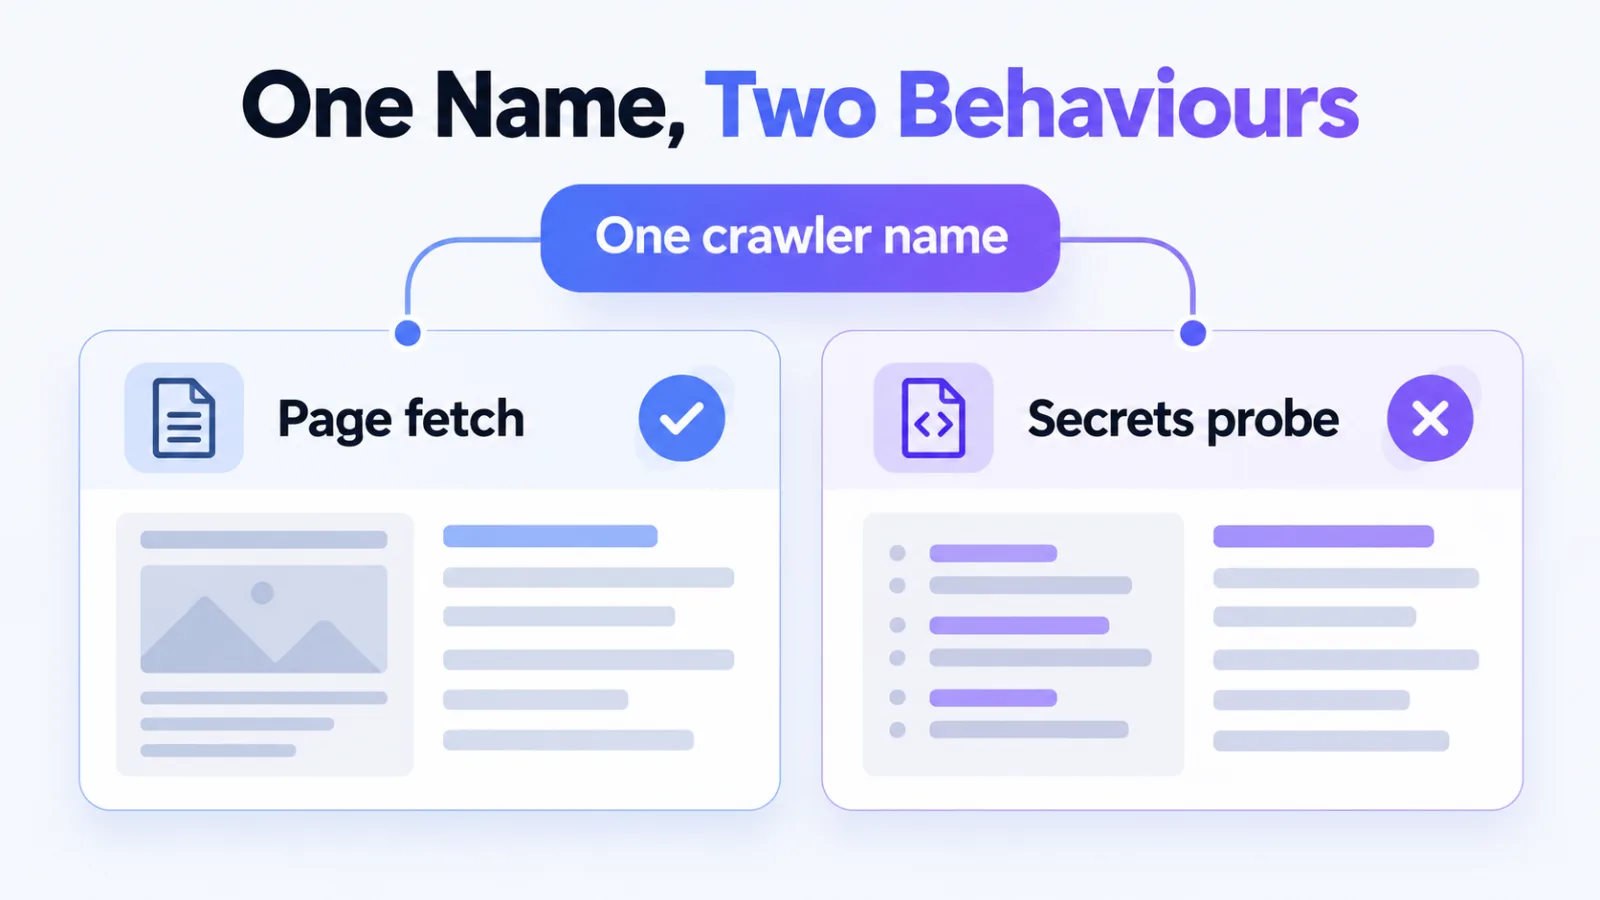
In 14 days, requests wearing 13 crawler names asked our server for .env files, private keys and credentials 1,179 times. Real crawlers don’t do that.
These were fake AI crawlers. Scanners borrow the user agent of ClaudeBot, GPTBot, Googlebot and others because a log tool files them under a name you trust. About one in three requests carrying ClaudeBot’s name was one of them.
Here’s how we measured it, which names got borrowed, what the server answered, and what it does to any count built on user agents.
What We Measured
Fourteen full days, 16 to 29 September 2026, from the web server’s access log.
- Counted: page requests, leaving out images, scripts and admin paths.
- Probe: a request for a path that holds secrets or server internals.
- Name: a crawler token found anywhere in the full user agent.
- Examples: .env, .git, credentials and /proc.
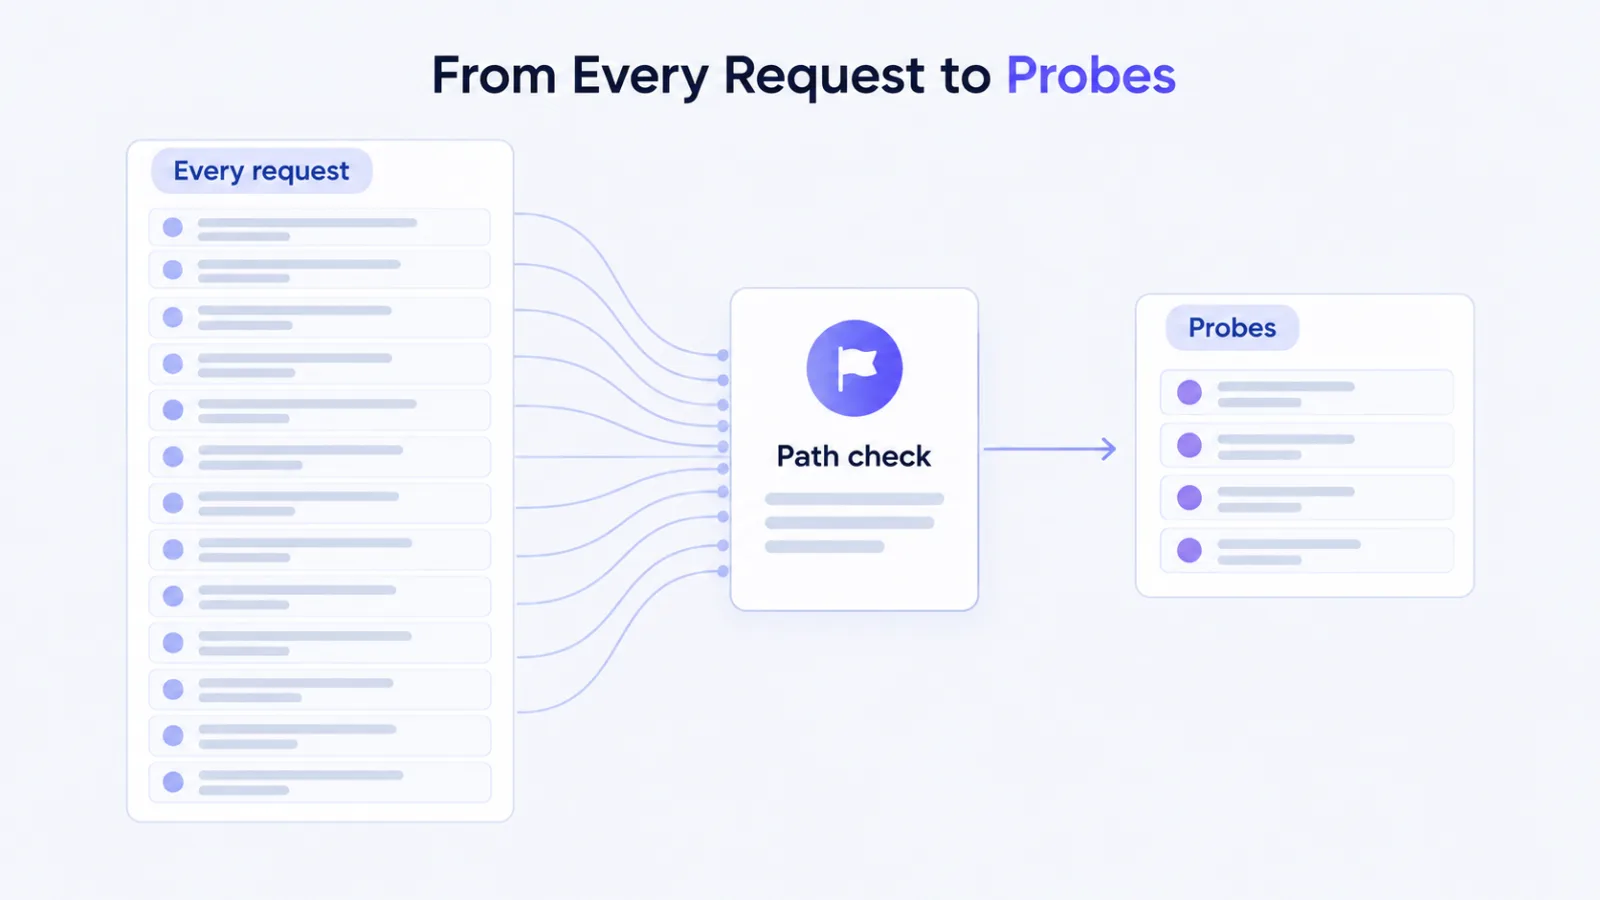
A crawler indexes pages that are linked or listed. It has no reason to ask for a file called .env, and no page on this site links to one.
Which Fake AI Crawlers Borrowed Which Names
Thirteen names carried at least one probe. The table shows how much of each name’s traffic it was.
| Crawler name | Requests | Secrets probes | Share probes |
|---|---|---|---|
| ClaudeBot | 730 | 254 | 35% |
| PerplexityBot | 562 | 129 | 23% |
| GPTBot | 241 | 92 | 38% |
| CCBot | 115 | 84 | 73% |
| Bytespider | 497 | 79 | 16% |
| cohere-ai | 116 | 79 | 68% |
| meta-externalagent | 251 | 76 | 30% |
| Amazonbot | 730 | 73 | 10% |
| Baiduspider | 205 | 71 | 35% |
| OAI-SearchBot | 447 | 71 | 16% |
| DuckAssistBot | 120 | 63 | 52% |
| Googlebot | 1,174 | 61 | 5% |
| ChatGPT-User | 393 | 47 | 12% |
Rows group a crawler’s family. The ClaudeBot row includes Claude-User and Claude-SearchBot, and the PerplexityBot row includes Perplexity-User.
Who never showed up as a probe
Bingbot, YandexBot, PetalBot, AhrefsBot, SemrushBot and MJ12bot made thousands of requests between them and not one probe. The borrowed names were AI, Google and Baidu names.
CCBot and cohere-ai are the starkest case. Not one request under either name returned a page in the whole window.
The names are copied exactly
The user agent on a probe is often identical to the one on a real fetch. Googlebot’s probes carried the same string as its legitimate page requests, character for character.
Nothing in the name separates them. That’s the whole trick.
What the Server Answered
Of the 1,179 probes, 950 got an error, 223 were redirected and 6 came back with a 200 status.
Those six are the reason to read the body and not the status. Each returned an ordinary page.
A request for .env returned our homepage, with no key-value lines in it. A request for a web framework’s remote-code path returned a normal page of ours. Nothing was exposed.
Check the body, not the status
A 200 on a path like that isn’t proof of a leak. What settles it is the content: a real environment file is lines of name=value pairs, and ours had none.
What Fake Crawlers Do to Your Counts
Named crawlers accounted for 11.8% of all probe requests. The other 88% arrived under other user agents, mostly ordinary browser strings, and those came every one of the 14 days.
The crawler-named probes were different. They came in bursts on 7 of the 14 days, with 304 on the busiest day, 20 September.
A count of ClaudeBot requests that includes them measures a scanner’s choice of costume. On this site 254 of the 730 requests carrying ClaudeBot’s name were probes, and any AI-visibility report built on user agents inherits that.
Three Checks That Separate Them
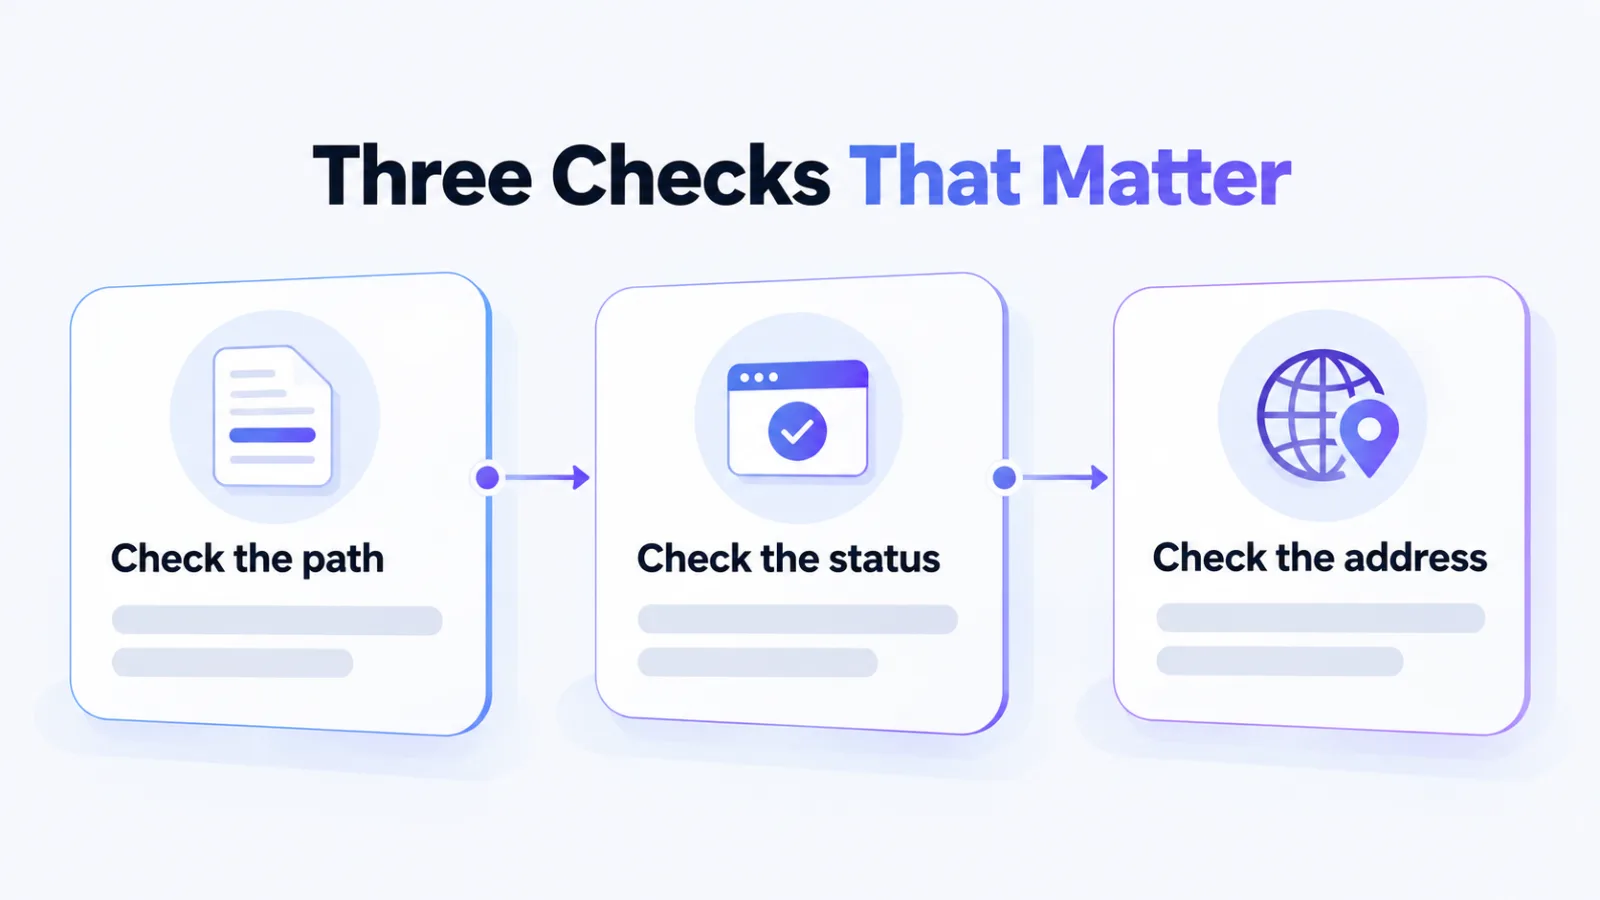
The name is the one field that proves nothing. Three others do the work.
- Check the path: did it ask for something no page links to?
- Check the status: real fetches mostly return pages, probes mostly return errors.
- Check the address: match it to the crawler’s published ranges.
- Never allow by name: a rule that trusts a user agent trusts the scanner too.
The address check needs the visitor’s real address in your log. Behind a proxy, that means logging the header it forwards, which is why we couldn’t run it here.
What the Numbers Don’t Prove
Four limits, and the first two matter most.
- We can’t name the sender: every logged address is Cloudflare’s.
- Not every request is fake: the same names also fetched real pages.
- One site, 14 days: that’s a case study, not a survey.
- Our path list: a narrower or wider list changes the shares.
We also tested whether one scanner was rotating through the names, and the data didn’t support it. The probe paths overlap between names, but only partly. So we’re not claiming one actor.
The word fake rests on behaviour. Requesting .env files and credentials under thirteen different crawler names, Googlebot’s among them, isn’t how any crawler operates.
How to Check Your Own Log
You need the access log for a stretch of complete days.
- List your probes: paths such as .env, .git and credentials.
- Group by name: count probes under each crawler token.
- Read the answers: statuses first, then the body of any 200.
- Compare shares: probes as a fraction of that name’s requests.
The same habit of reading raw log lines caught the fake Google referrals we measured earlier.
Our study of new page crawl times shows what real crawler arrivals look like once the noise is filtered out.
Frequently Asked Questions
Are fake AI crawlers a security risk
The requests only matter if your server exposes the file. On our site every probe returned an error, a redirect or an ordinary page. Check what your server returns for .env instead of assuming.
How can I tell a real AI crawler from a fake one
You can look at what it asked for and what it got. A real crawler fetches linked pages. For a firm answer, match the address to the operator’s published ranges or run a reverse lookup.
Why does my log show ClaudeBot requesting .env files
It’s most likely a scanner borrowing the name, because a crawler has no reason to ask for a file called .env. The same request also arrives under Googlebot’s name.
Should I block AI crawlers because of this
No. Blocking by name stops the real crawler and lets the scanner switch names. Block the probe paths and verify crawlers by address.
Do fake crawlers inflate AI visibility reports
Any report that counts requests by user agent can be inflated. On this site, between 5% and 73% of the requests under a crawler’s name were probes, depending on the name.
Does a 200 on .env mean I’m leaking secrets
Not by itself. Read the body. Ours returned the homepage, and a real leak is lines of name=value pairs.
Count the Costume, Then the Crawler
A crawler name in a log is a claim, and this site’s log made it thirteen times for requests no crawler would send.
Run the probe count on your own last 14 days before you trust a bot report.